CPU HPL in Practice: from Single Node to 80 Nodes
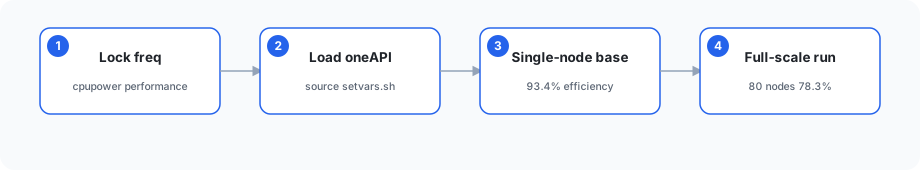
Abstract: This is a post-mortem of real runs, not a theory chapter. Following "single-node tuning → small-scale scaling → full-scale acceptance", here are the HPL.dat configs, commands, and measured results at every stage, plus every pitfall hit along the way.
1. Test Environment (sanitized)
| Item | Spec |
|---|---|
| CPU | dual-socket, 52 physical cores/socket, 104 cores/node, 2.0 GHz |
| ISA | AVX-512 (32 DP FLOPs/cycle) |
| Memory | 1536 GB / node |
| Software | Intel oneAPI (MKL + MPI), HPL 2.3 |
| Interconnect | Ethernet / InfiniBand |
| Rpeak / node | 6656 GFlops |
Load oneAPI first (every session)
source /opt/intel202*/oneapi/setvars.sh intel64 --force
which mpirun   # confirm it resolves, or everything fails
2. Step 0: Lock Frequency for Reproducibility
# on all nodes
cpupower -c all frequency-set -g performance

# spot-check real frequency and load
turbostat   # expect Avg_MHz ≈ 2.1GHz, Busy% = 100
BIOS (three key settings)
- CPU Power and Performance Policy → Performance
- Hyper-Threading: off for testing (104 physical cores is enough)
- Turbo Boost → Enabled
3. Single-Node Baseline
Size via N_calculator.calculator (90% memory):
N = 430746 (90% memory) Rpeak = 6656.0 GFlopsBatch run across 91 nodes (excerpt):
| Node | Measured GFlops | Efficiency |
|---|---|---|
| node 01 | 6329.63 | 95.1% |
| node 31 | 6282.68 | 94.4% |
| node 35 | 6433.05 | 96.6% (best) |
| node 40 | 5843.34 | 87.8% |
| node 53 | 5792.35 | 87.0% |
| node 54 | 5777.46 | 86.8% (worst) |
| cluster avg | ~6218 | 93.4% |
Baseline: 93.4% average efficiency. Nodes below 90% get individual inspection.
4. 36-Node Run (Mid Scale)
4.1 HPL.dat key parameters
N     : 1000000
NB    : 384
P     : 12
Q     : 6        (P × Q = 72 = 36 nodes × 2 ranks/node)
4.2 Command
mpirun -perhost 2 -np 72 -hostfile hostfile ./runme_intel64_prv4.3 Result
| Item | Value |
|---|---|
| Rpeak | 239616 GFlops |
| Measured | 191494 GFlops (1.91494e+05) |
| Efficiency | 79.9% |
| Runtime | 3481.4 s (~58 min) |
| Residual check | PASSED |
5. 80-Node Run (Full-Scale Acceptance)
5.1 HPL.dat key parameters
N     : 3145728
NB    : 384
P     : 10
Q     : 8        (P × Q = 80 ranks, 1 rank/node)
5.2 Script / command
export MPI_PROC_NUM=80
export MPI_PER_NODE=1
export NUMA_PER_MPI=2

mpirun -perhost ${MPI_PER_NODE} -np ${MPI_PROC_NUM} -f 2.txt ./runme_intel64_prv | tee -a 80cpulinpack.txt
5.3 Result
| Item | Value |
|---|---|
| Rpeak | 532480 GFlops |
| Measured | 417170 GFlops (4.17170e+05) |
| Efficiency | 78.34% |
| Runtime | 49746.14 s (~13.8 h) |
| Residual check | 1.84674053e-03 ...... PASSED |
T/V                N    NB     P     Q               Time                 Gflops
WC00C2R2     3145728   384    10     8           49746.14            4.17170e+05
6. Scaling Curve (Measured)
| Scale | Rpeak GFlops | Measured GFlops | Efficiency | Runtime |
|---|---|---|---|---|
| 1 node (avg) | 6656 | 6218 | 93.4% | — |
| 36 nodes | 239616 | 191494 | 79.9% | 58 min |
| 80 nodes | 532480 | 417170 | 78.3% | 13.8 h |
Three patterns: ① efficiency drops as scale grows; ② 78–80% is the real level at 36–80 nodes; ③ large runs are time-expensive (14 h per 80-node run) — plan schedules accordingly.
7. Pitfalls
7.1 Pit 1: mpirun: command not found
./runme_intel64_dynamic: line 86: mpirun: command not foundCause: fresh shell without source setvars.sh. Fix:
source /opt/intel202*/oneapi/setvars.sh intel64 --force7.2 Pit 2: inconsistent directories across nodes
Every compute node must see the same HPL directory (binaries, HPL.dat, hostfile), e.g. via NFS; otherwise MPI ranks fail to start on some nodes.
7.3 Pit 3: ignoring the residual line
Only a PASSED final line makes results usable; FAILED means unstable factorization (usually N too large for memory or mismatched NB).
8. Takeaway
- Single node 93.4% → 36 nodes 79.9% → 80 nodes 78.3%: reuse this efficiency curve for similar acceptance estimates.
- Before full scale: lock frequency → load oneAPI → sync directories → small-scale sanity run — avoid wasting a 14-hour run.
See CPU Theoretical Peak Calculation and Estimating HPL Performance for the theory and estimation side.